
 Home
 Publications
 Photo Gallery

I am a Research Scientist at Adobe Research, where I lead multiple research-to-production projects in generative image and video editing. My work spans unified editing frameworks (EditVerse, ICLR'26 Oral), generative video propagation (GenProp, Adobe MAX Sneak 2025), and physically-grounded shadow understanding (MetaShadow, shipped in Lightroom & Photoshop). I am equally driven by fundamental questions — how should we train visual generative models from scratch, and can editing and generation be unified into a single paradigm? These threads are converging on my broader vision: building world-aware visual foundation models that inherently understand the physical constraints of our world. I received my Ph.D. from The Chinese University of Hong Kong, advised by Prof. Chi-Wing Fu. When I'm not pushing pixels through neural networks, I'm exposing them on film — a slower way of seeing that keeps me close to the beauty I'm trying to teach machines to understand.
Publications
Click a paper to see details
Selected Works

Chimera: Designing and Chinchilla-Scaling Hybrid Visual Diffusion Transformers
Summary & resources
A hybrid visual diffusion backbone that replaces most full attention with linear attention, paired with Chinchilla-style scaling laws that make its compute-optimal training recipe predictable.
paperFull details & citationChongjian Ge*§†, Hanwen Jiang*§, Tianyu Wang*§, Jiuxiang Gu§, Yiran Xu§, Ziwen Chen§, Shaoteng Liu, Jing Shi, Yicong Hong, Zefan Cai, Hailin Jin, Hao Tan†
EditVerse: Unifying Image and Video Editing and Generation with In-Context Learning
Summary & resources
A unified framework for image and video generation and editing that leverages self-attention for in-context learning and cross-modal knowledge transfer.
paperprojectFull details & citationXuan Ju, Tianyu Wang, Yuqian Zhou, He Zhang, Qing Liu, Nanxuan Zhao, Zhifei Zhang, Yijun Li, Yuanhao Cai, Shaoteng Liu, Daniil Pakhomov, Zhe Lin, Soo Ye Kim†, Qiang Xu†
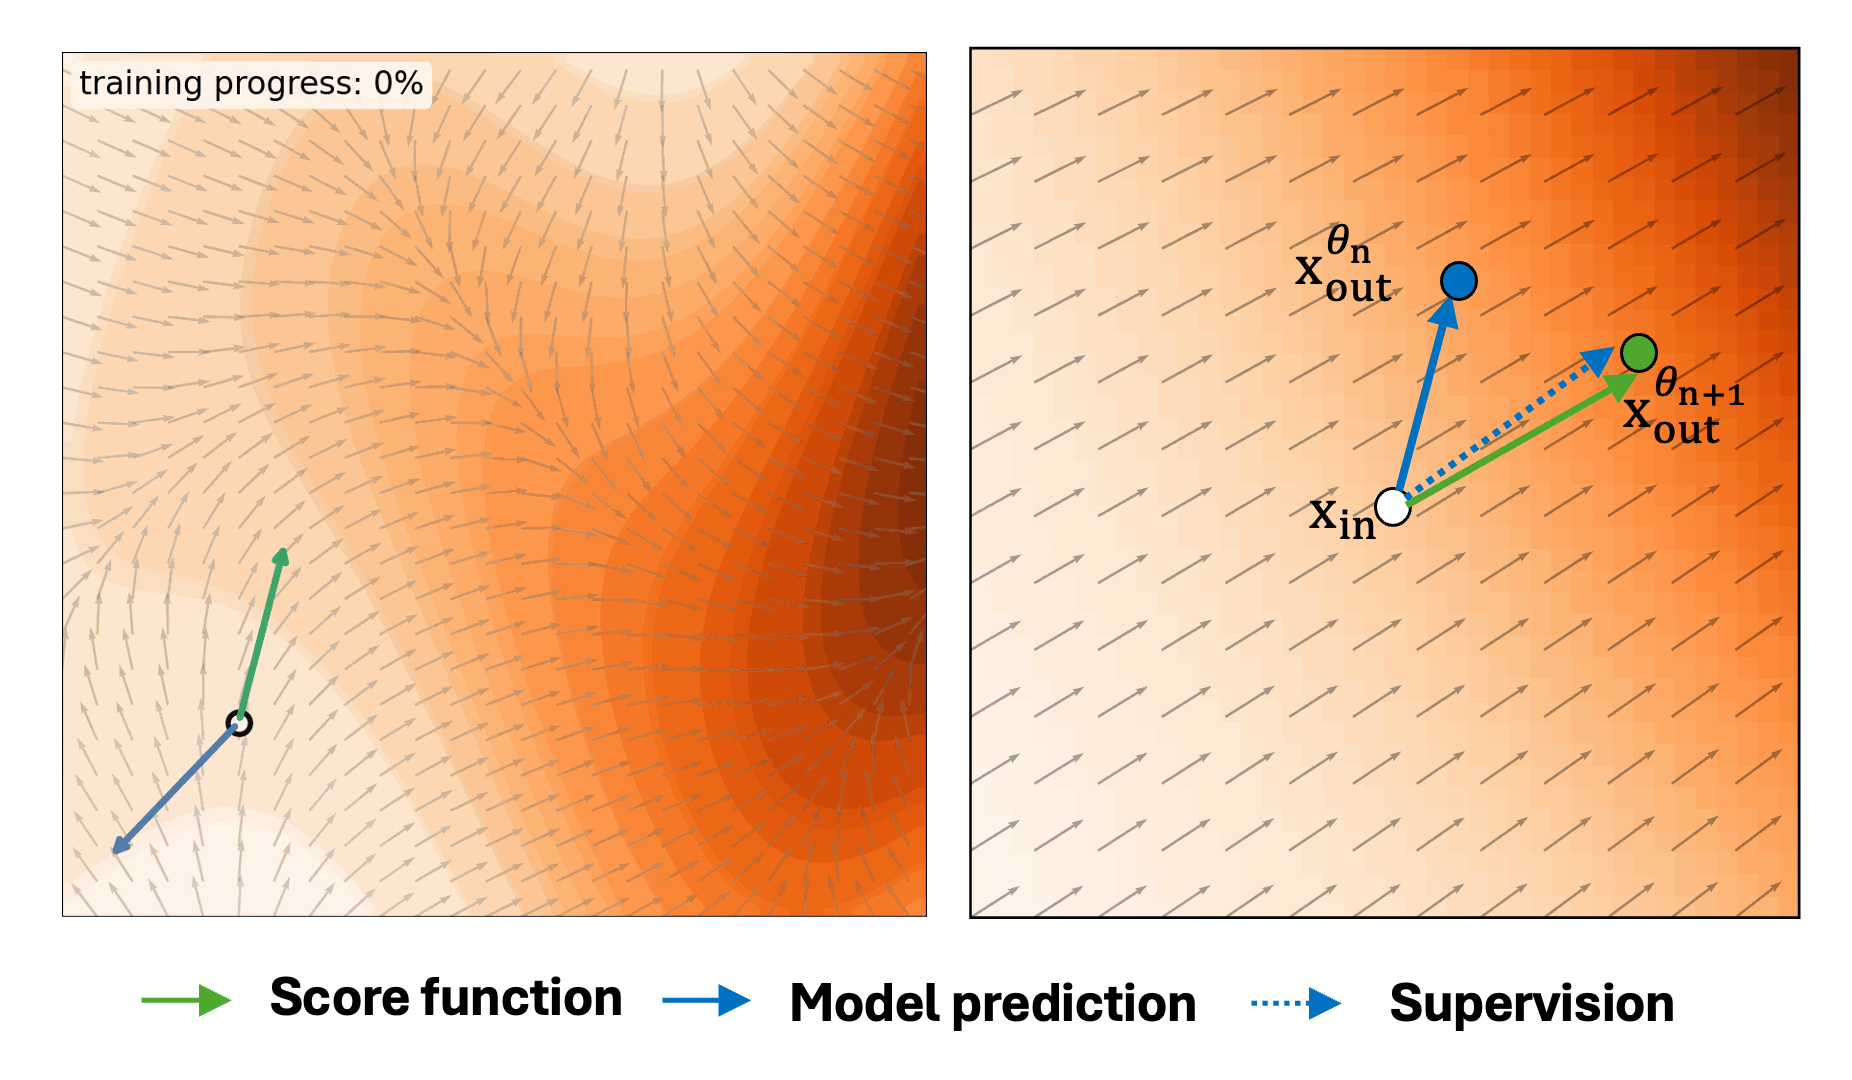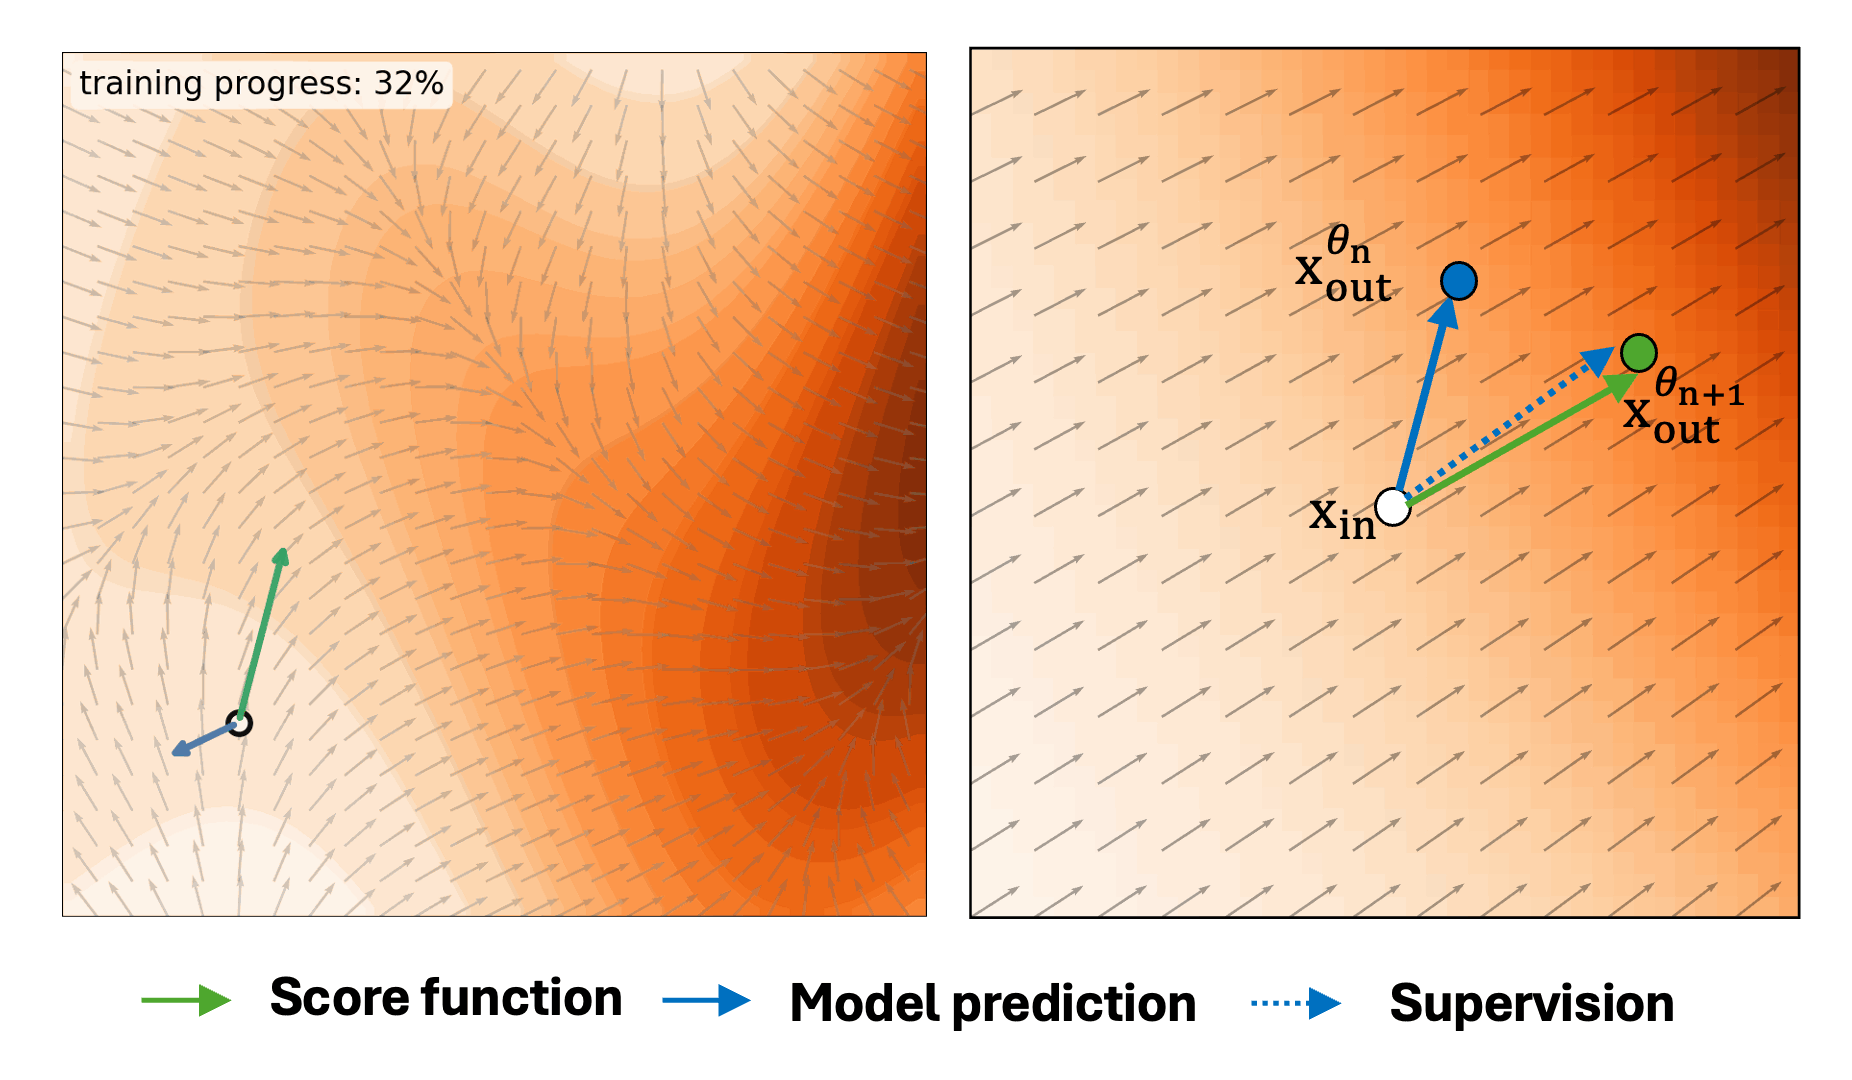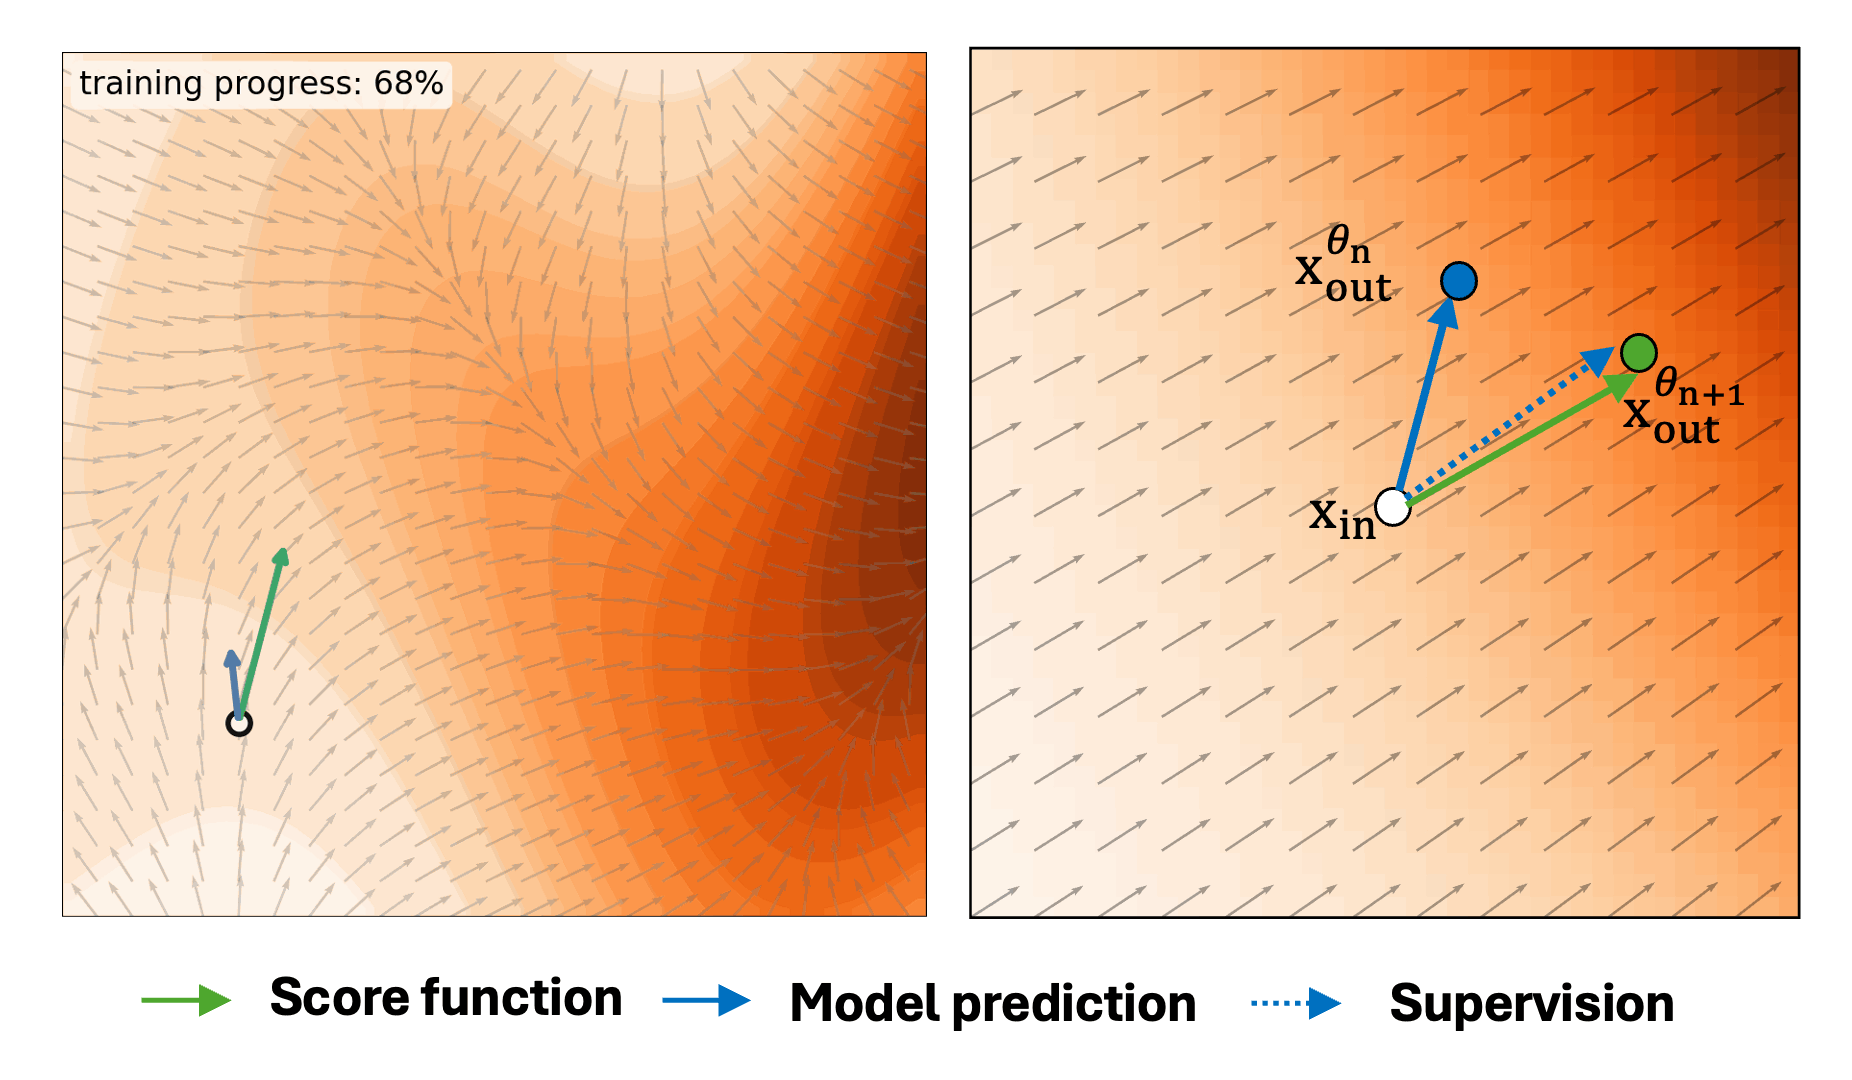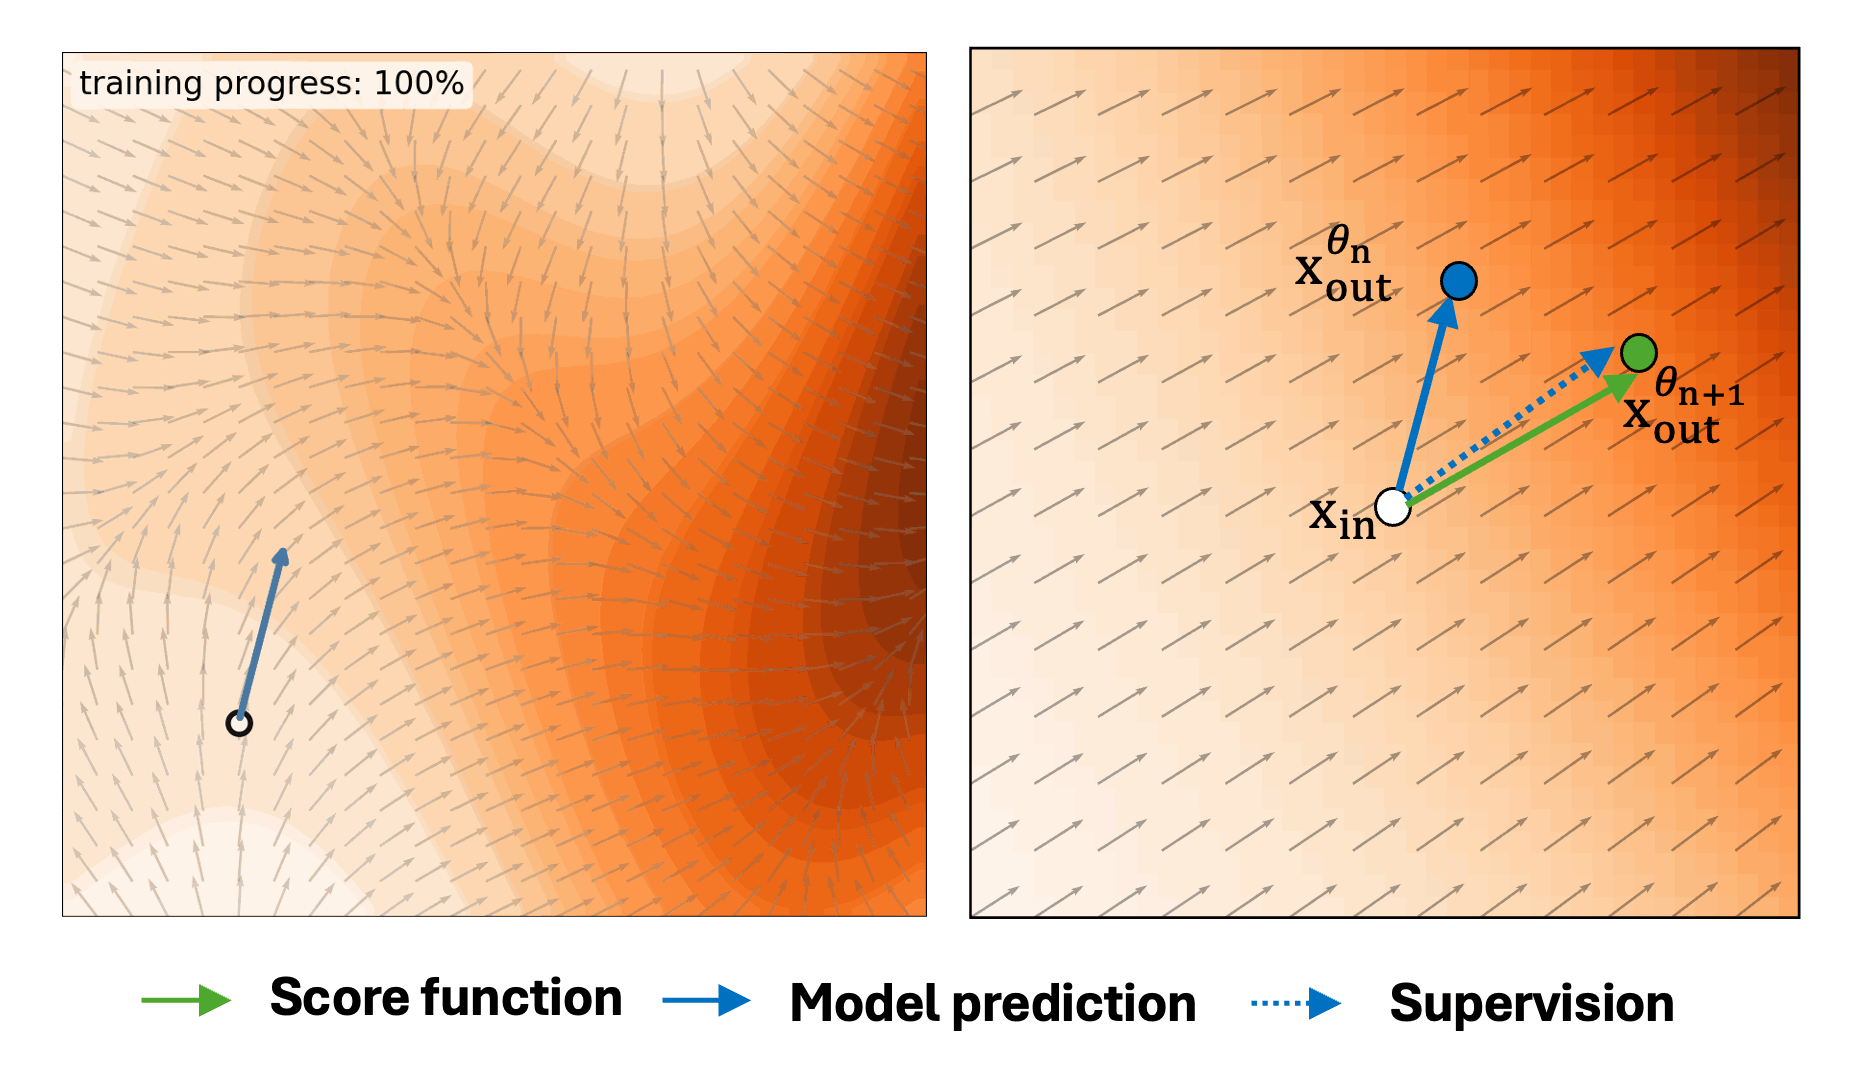
Self-Evaluation Unlocks Any-Step Text-to-Image Generation
Summary & resources
A from-scratch training approach for text-to-image generation that supports any-step inference using self-evaluation mechanism.
paperprojectFull details & citationXin Yu, Xiaojuan Qi†, Zhengqi Li, Kai Zhang, Richard Zhang, Zhe Lin, Eli Shechtman, Tianyu Wang†, Yotam Nitzan†
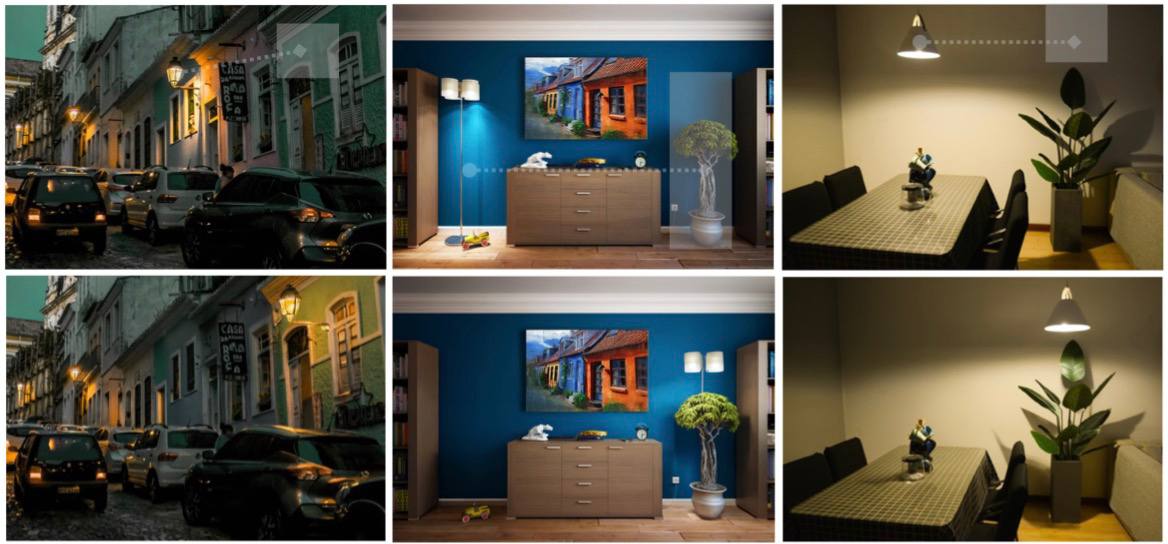
LightMover: Towards Precise and Efficient Control for Light Movement
Summary & resources
A framework for precise and efficient control of light movement in images, enabling physically plausible relighting and shadow manipulation.
Full details & citationGengze Zhou, Tianyu Wang, Soo Ye Kim, Zhixin Shu, Xin Yu, Yannick Hold-Geoffroy, Sumit Chaturvedi, Qi Wu, Zhe Lin, Scott Cohen
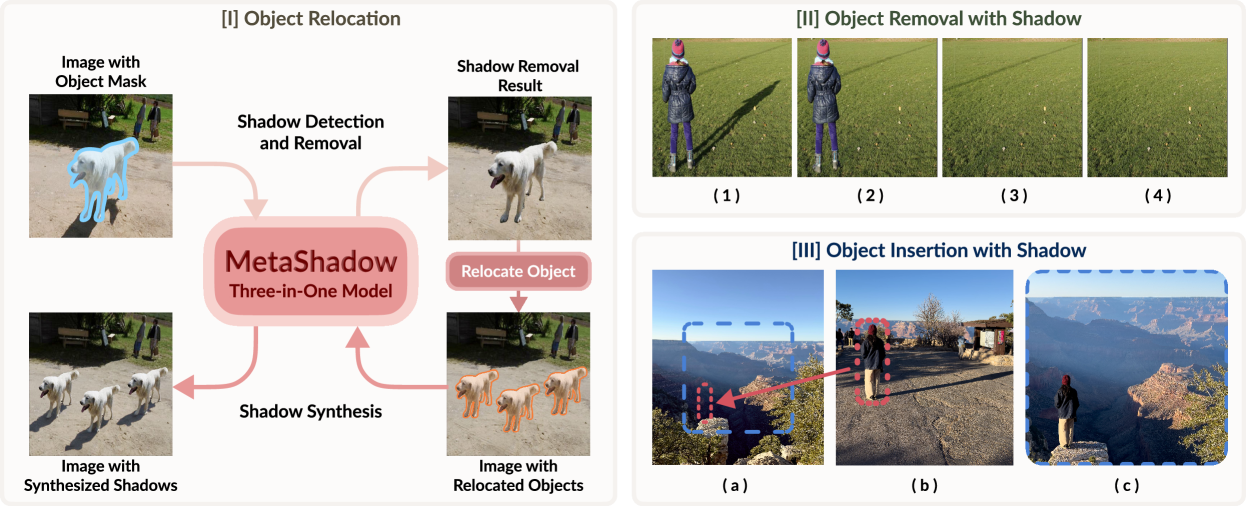
MetaShadow: Object-Centered Shadow Detection, Removal, and Synthesis
Summary & resources
A three-in-one framework for object-centered shadow detection, removal, and controllable synthesis in natural images.
paperpreprintFull details & citationTianyu Wang, Jianming Zhang, Haitian Zheng, Zhihong Ding, Scott Cohen, Zhe Lin, Wei Xiong, Chi-Wing Fu, Luis Figueroa†, Soo Ye Kim†
Generative Video Propagation
Summary & resources
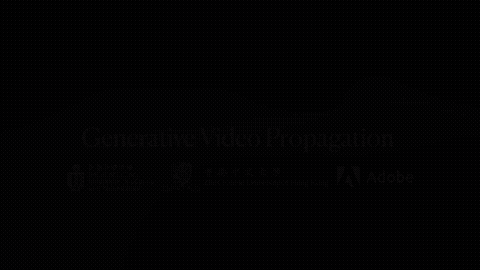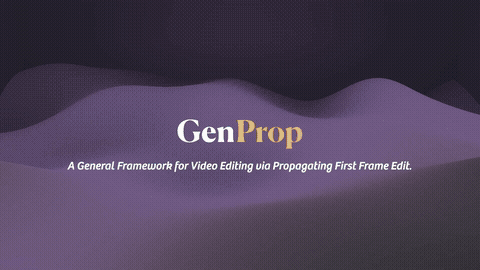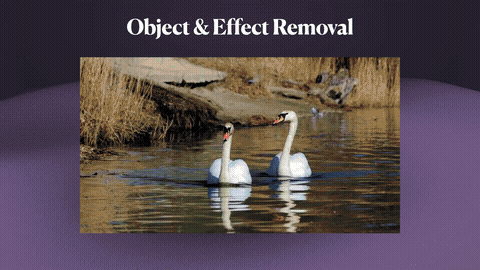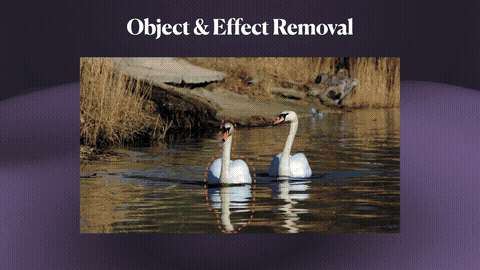
A unified framework that propagates edits from the first frame to all following frames using video generation models.
paperprojectpreprintFull details & citationShaoteng Liu, Tianyu Wang, Jui-Hsien Wang, Qing Liu, Zhifei Zhang, Joon-Young Lee, Yijun Li, Bei Yu, Zhe Lin, Soo Ye Kim†, Jiaya Jia†
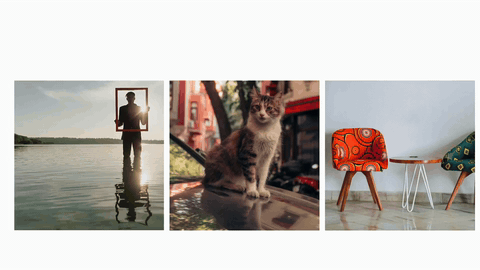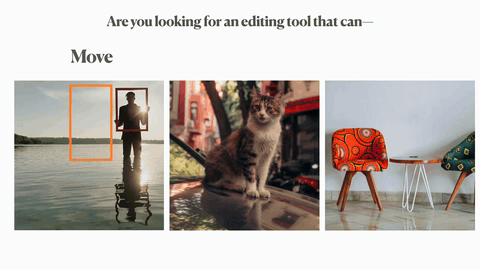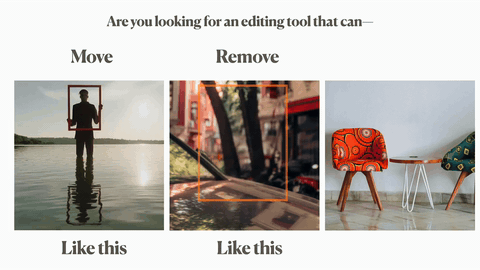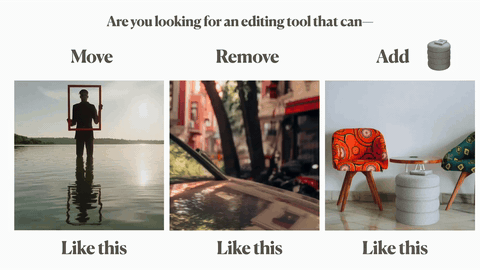
ObjectMover: Generative Object Movement with Video Prior
Summary & resources
A generative model for moving objects in images with accurate pose adjustment, lighting re-harmonization, and shadow/reflection synthesis.
paperprojectvideoFull details & citationXin Yu, Tianyu Wang, Soo Ye Kim, Paul Guerrero, Xi Chen, Qing Liu, Zhe Lin, Xiaojuan Qi†
More Publications (16)
RetouchIQ: MLLM Agents for Instruction-Based Image Retouching with Generalist Reward
Summary & resources
An MLLM-based agent framework for instruction-driven image retouching with a generalist reward model.
Full details & citationQiucheng Wu, Jing Shi, Simon Jenni, Kushal Kafle, Tianyu Wang, Shiyu Chang, Handong Zhao
OmniVCus: Feedforward Subject-driven Video Customization with Multimodal Control Conditions
Summary & resources
A diffusion Transformer framework for multi-subject video customization with multimodal control conditions, featuring a data construction pipeline for training without labels.
paperprojectcodeFull details & citationYuanhao Cai, He Zhang, Xi Chen, Jinbo Xing, Yiwei Hu, Yuqian Zhou, Kai Zhang, Zhifei Zhang, Soo Ye Kim, Tianyu Wang, Yulun Zhang, Xiaokang Yang, Zhe Lin, Alan Yuille
Unveiling Deep Shadows: A Survey and Benchmark on Image and Video Shadow Detection, Removal, and Generation in the Deep Learning Era
Summary & resources
A comprehensive survey and benchmark covering the past decade of shadow detection, removal, and generation research in deep learning.
papercodeFull details & citationXiaowei Hu, Zhenghao Xing, Tianyu Wang, Chi-Wing Fu, Pheng-Ann Heng
Video Instance Shadow Detection Under the Sun and Sky
Summary & resources
A semi-supervised framework for video instance shadow detection using contrastive learning and cycle consistency.
paperFull details & citationZhenghao Xing, Tianyu Wang, Xiaowei Hu, Haoran Wu, Chi-Wing Fu, Pheng-Ann Heng
Learning Weather-General and Weather-Specific Features for Image Restoration Under Multiple Adverse Weather Conditions
Summary & resources
A unified framework for image restoration that learns both weather-general and weather-specific features to handle multiple adverse conditions.
paperFull details & citationYi Zhu, Tianyu Wang, Xueyang Fu◯, Xin Yang, Xuejin Guo, Jiabin Dai, Yu Qiao, Xiaowei Hu◯
H2ONet: Hand-Occlusion-and-Orientation-aware Network for Real-time 3D Hand Mesh Reconstruction
Summary & resources
A network for real-time 3D hand mesh reconstruction that handles hand occlusion and orientation challenges.
papervideocodeFull details & citationHao Xu, Tianyu Wang, Xiao Tang, Chi-Wing Fu
SILT: Shadow-aware Iterative Label Tuning for Learning to Detect Shadows from Noisy Labels
Summary & resources
A method for learning shadow detection from noisy labels using iterative label tuning with shadow-aware mechanisms.
paperFull details & citationHan Yang*, Tianyu Wang*, Xiaowei Hu, Chi-Wing Fu
Instance Shadow Detection with a Single-Stage Detector
Summary & resources
Journal extension of CVPR 2021 work with improved single-stage detector for instance shadow detection and shadow-object association.
papercodeFull details & citationTianyu Wang, Xiaowei Hu, Pheng-Ann Heng, Chi-Wing Fu
Sparse2Dense: Learning to Densify 3D Features for 3D Object Detection
Summary & resources
A framework to boost 3D detection by learning to densify point clouds in latent space, improving detection of small and distant objects.
papercodeFull details & citationTianyu Wang, Xiaowei Hu, Zhengzhe Liu, Chi-Wing Fu
Single-Stage Instance Shadow Detection With Bidirectional Relation Learning
Summary & resources
A single-stage approach for detecting instance-level shadows using bidirectional relation learning between objects and their shadows.
papervideocodeFull details & citationTianyu Wang, Xiaowei Hu†, Chi-Wing Fu, Pheng-Ann Heng
Revisiting Shadow Detection: A New Benchmark Dataset for Complex World
Summary & resources
A comprehensive benchmark dataset for shadow detection in complex real-world scenarios.
paperdatasetcodeFull details & citationXiaowei Hu, Tianyu Wang, Chi-Wing Fu, Yitong Jiang, Qiong Wang, Pheng-Ann Heng
Instance Shadow Detection
Summary & resources
First work to tackle instance-level shadow detection, associating each shadow with its corresponding object instance.
paperdatasetcodeFull details & citationTianyu Wang, Xiaowei Hu, Qiong Wang, Pheng-Ann Heng, Chi-Wing Fu
Single-Image Real-Time Rain Removal Based on Depth-Guided Non-Local Features
Summary & resources
Real-time rain removal using depth-guided non-local features for robust image restoration.
paperdatasetcodeFull details & citationXiaowei Hu, Lei Zhu, Tianyu Wang, Chi-Wing Fu, Pheng-Ann Heng
SAC-Net: Spatial Attenuation Context for Salient Object Detection
Summary & resources
Spatial attention mechanism for salient object detection using context attenuation.
paperresultscodeFull details & citationXiaowei Hu, Chi-Wing Fu, Lei Zhu, Tianyu Wang, Pheng-Ann Heng
Spatial Attentive Single-Image Deraining with a High Quality Real Rain Dataset
Summary & resources
Spatial attention network for single-image deraining with a new high-quality real-world rain dataset.
paperdatasetdataset_baiducodeFull details & citationTianyu Wang, Xin Yang, Ke Xu, Shaozhe Chen, Qiang Zhang, Rynson W.H. Lau†
Towards Accurate Alignment in Real-time 3D Hand-Mesh Reconstruction
Summary & resources
Real-time 3D hand mesh reconstruction with improved alignment accuracy.
papercodeFull details & citationXiao Tang, Tianyu Wang, Chi-Wing Fu
Film Photography
 01▲
 02▲
 03▲
 04▲
 05▲
 06▲
 07▲
 08▲
 09▲
 10▲
 11▲
 12▲
 13▲
 14▲
 15▲
 16▲
 17▲
 18▲
 19▲
 20▲
 21▲
 22▲
 23▲
 24▲
 25▲
 26▲
 27▲
 28▲
 29▲
 30▲
 31▲
 32▲
 33▲
 34▲
 35▲
 36▲
 37▲
 38▲
 39▲
 40▲
 41▲
 42▲
 43▲
 44▲
 45▲
 46▲
 47▲
 48▲
 49▲
 50▲
 51▲
 52▲
 53▲
 54▲
 55▲
 56▲
 57▲
 58▲
 59▲
 60▲
 61▲
 62▲
 63▲
 64▲
 65▲
 66▲
 67▲
 68▲
 69▲
 70▲
 71▲
 72▲
 73▲
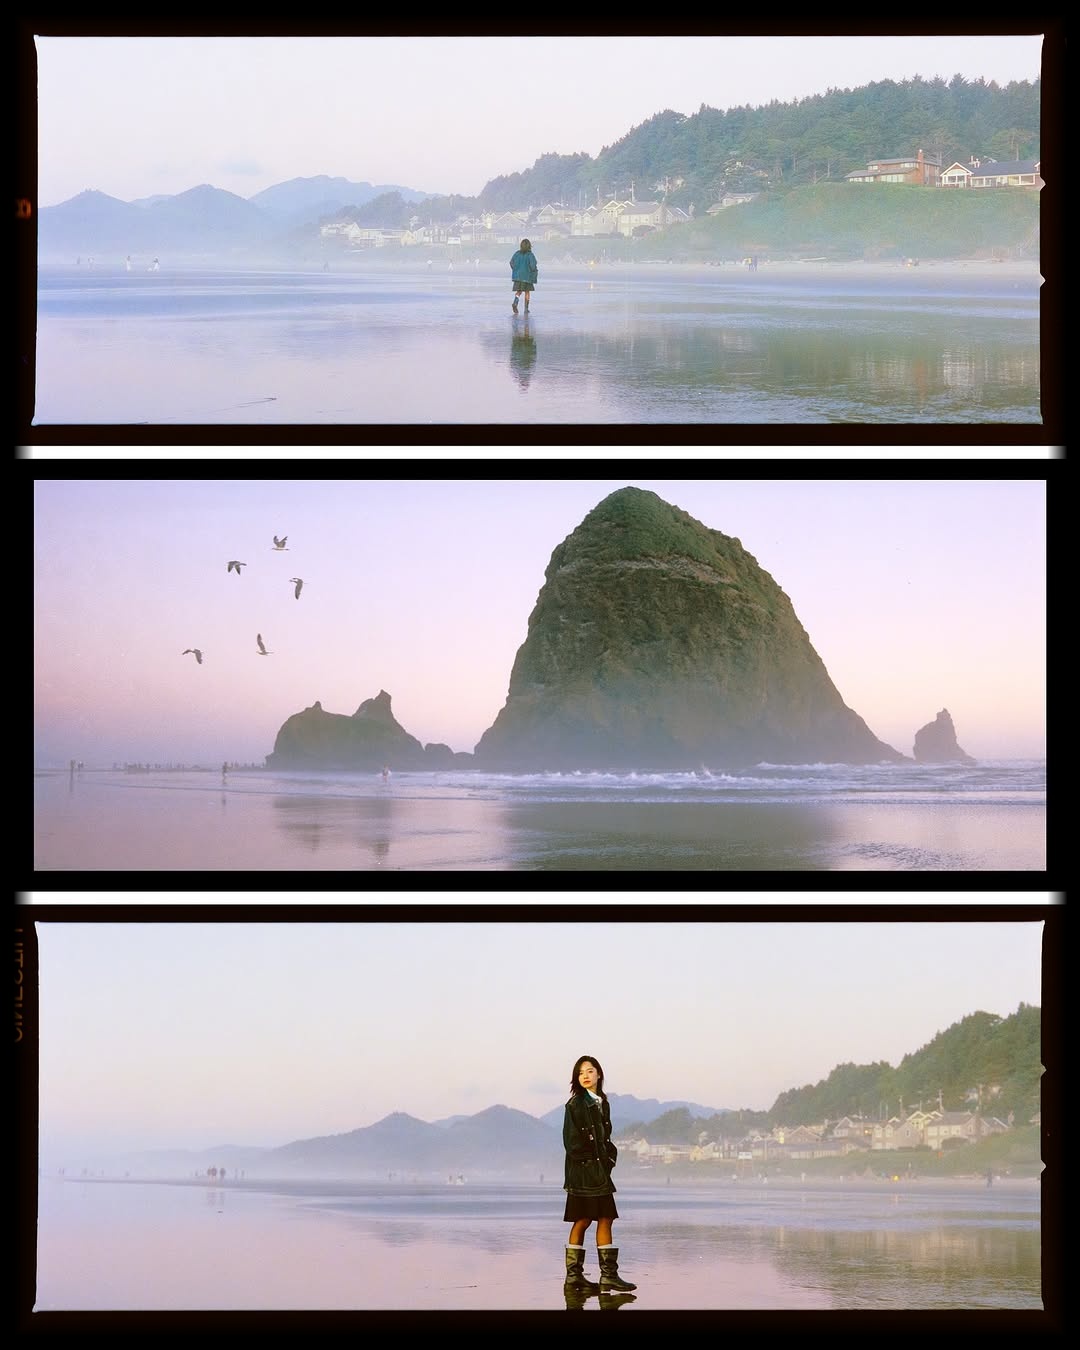 74▲
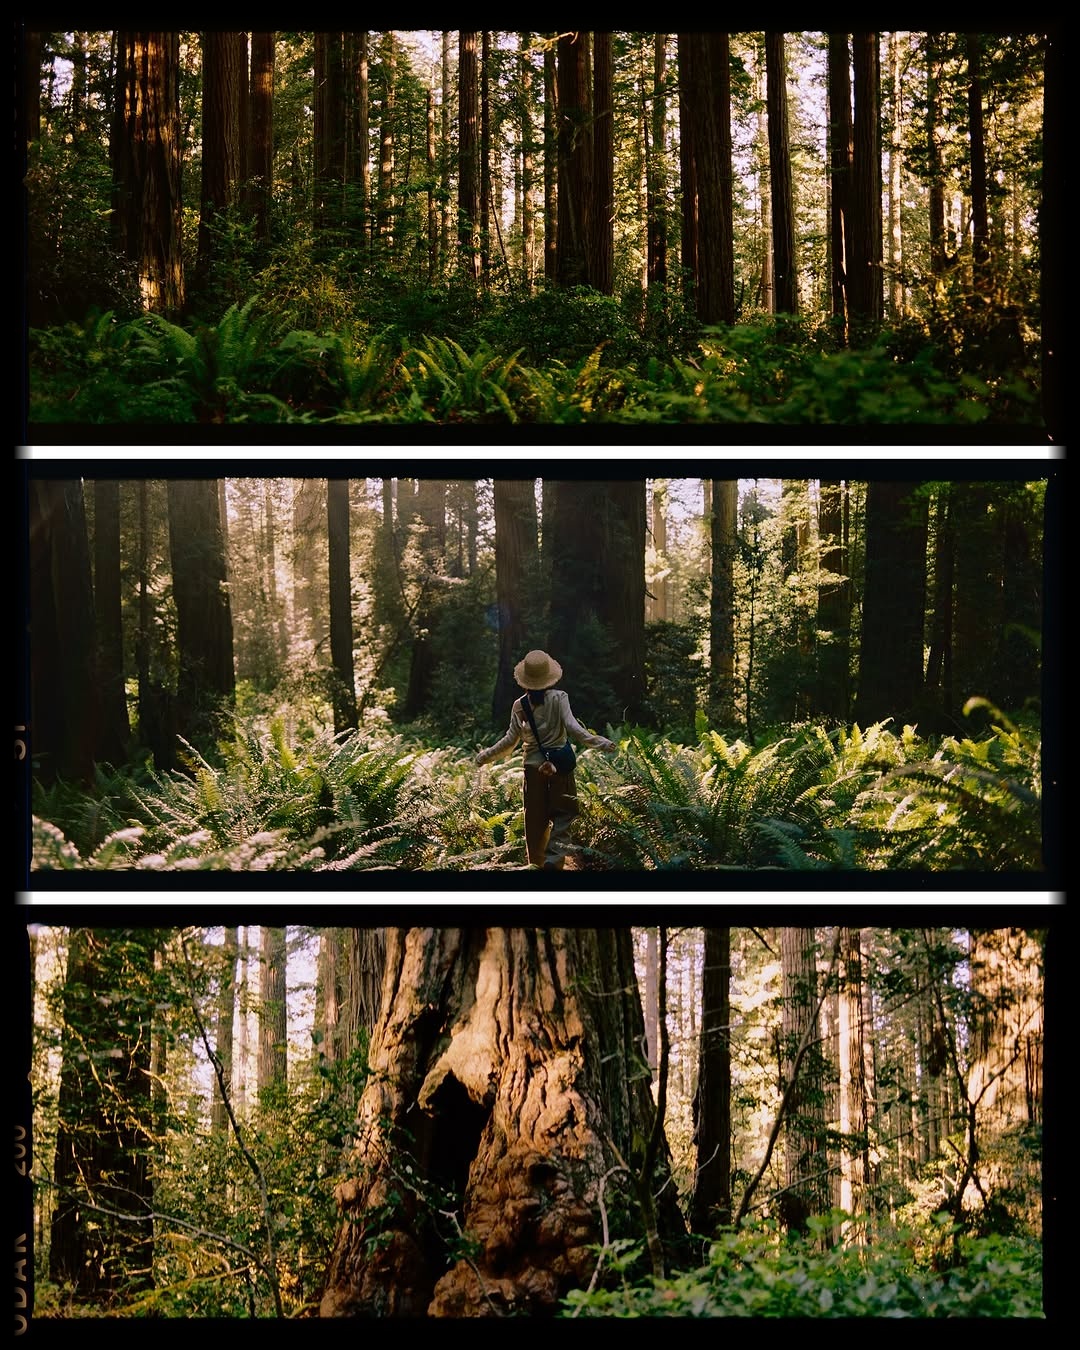 75▲
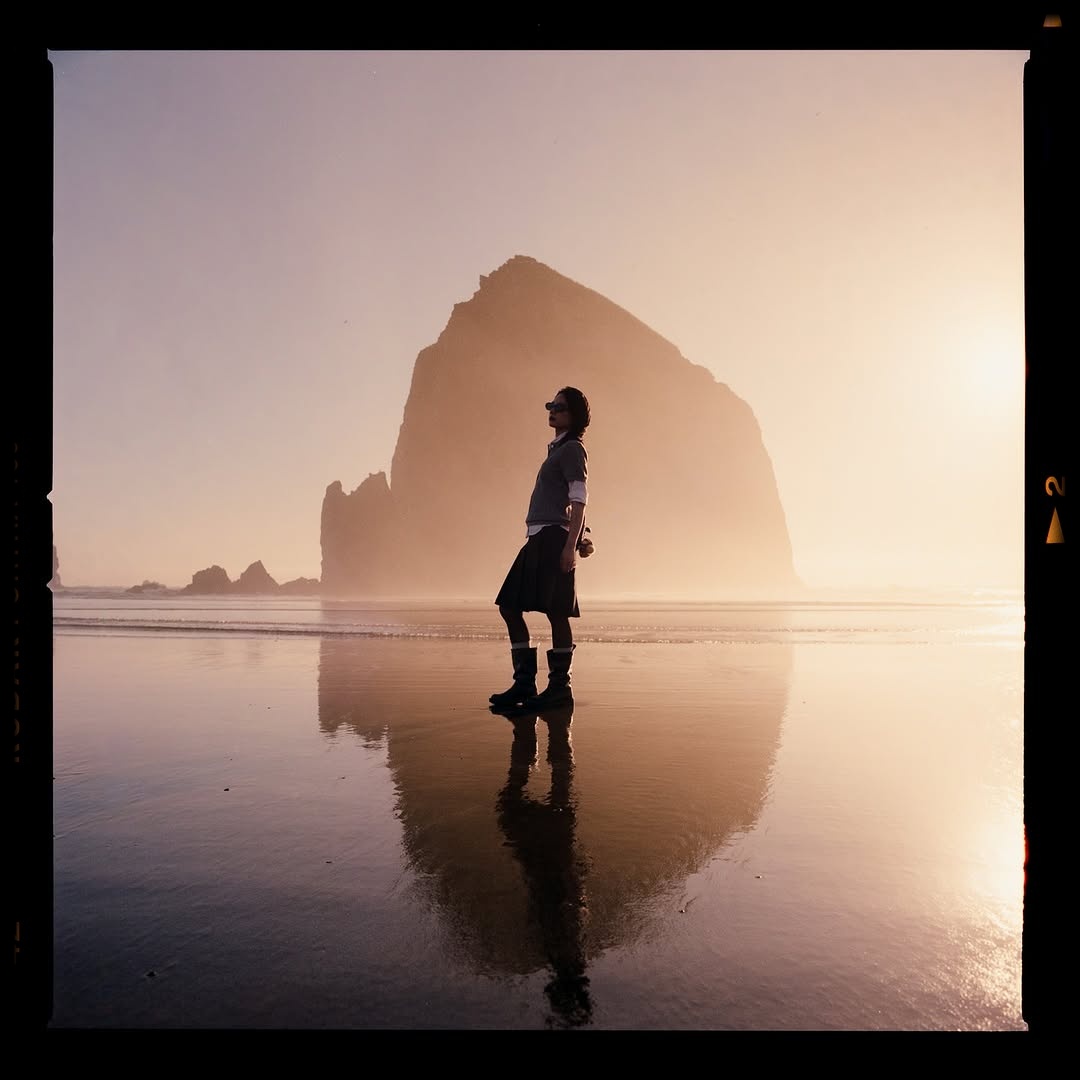 76▲
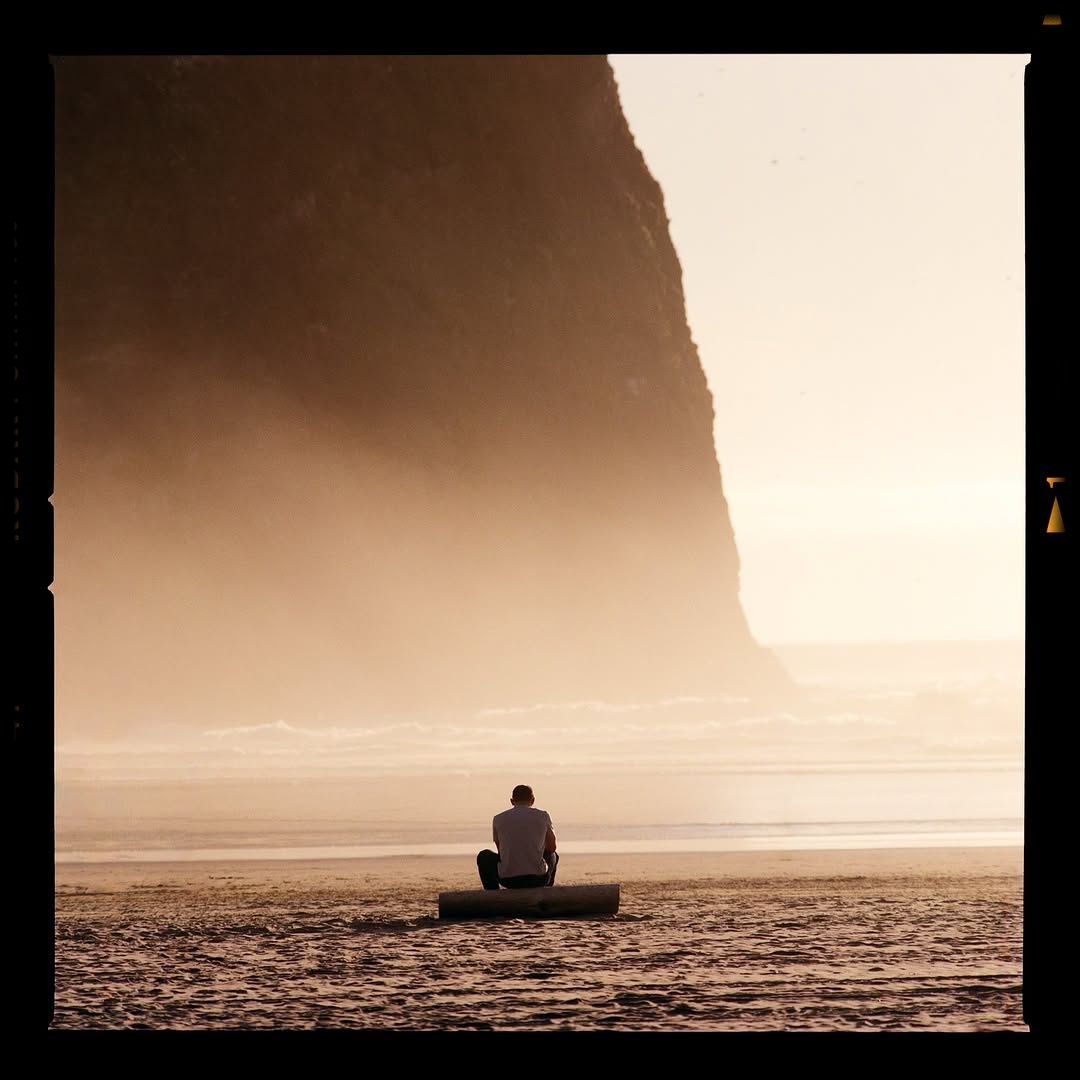 77▲
 78▲
 79▲
 80▲
 81▲
 82▲
 83▲
 84▲
 85▲
 86▲
 87▲
 88▲
 89▲
 90▲
 91▲
 92▲
 93▲
 94▲
 95▲
 96▲
 97▲
 98▲
 99▲
 100▲
 101▲
 102▲
 103▲
 104▲
 105▲
 106▲
 107▲
 108▲
 109▲
 110▲
 111▲
 112▲
 113▲
 114▲
 115▲
 116▲
 117▲
 118▲
 119▲
 120▲
 121▲
 122▲
 123▲
 124▲
 125▲
 126▲
 127▲
 128▲
 129▲
 130▲
 131▲
 132▲
 133▲
 134▲
 135▲
 136▲
 137▲
 138▲
 139▲
 140▲
 141▲
 142▲
 143▲
 144▲
 145▲
 146▲
 147▲
 148▲
 149▲
 150▲
 151▲
 152▲
 153▲
 154▲
 155▲
 156▲
 157▲
 158▲
 159▲
 160▲
 161▲
 162▲
 163▲
 164▲
 165▲
 166▲
 167▲
 168▲
 169▲
 170▲
 171▲
 172▲
 173▲
 174▲
 175▲
 176▲
 177▲
 178▲
 179▲
 180▲
 181▲
 182▲
 183▲
 184▲
 185▲
 186▲
 187▲